Education voucher at hand? Step into the fast lane: Contact us
Contact us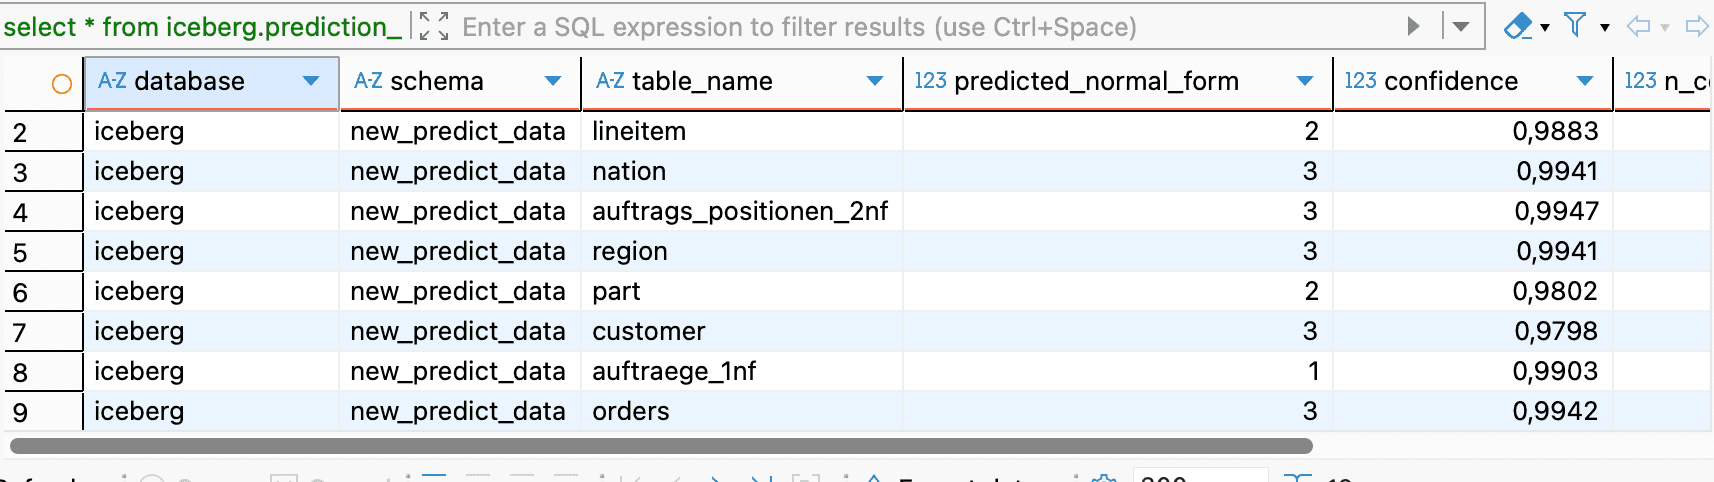
Alligator Metaswamp
Alligator Metaswamp is an ML-powered service that predicts database schema properties from metadata alone—without accessing row data. It identifies Primary Keys (single and composite), Foreign Keys (single and composite), Normalization Forms (0–3NF), and Domain Grouping (Subject Areas) for undocumented databases. The system is built around four ML classification tasks, each generating a dedicated model: single and composite primary key detection, single and composite foreign key detection, normal form prediction (0–3NF), and subject-area discovery. Features are engineered from database metadata and column-level statistics like cardinality, data types, and null patterns—never the actual records themselves. Training data spans 60+ public, synthetic, and real-world databases (Kaggle, TPC-H, Northwind, Spider, MIMIC-IV, and others) across domains including e-commerce, healthcare, finance, and engineering. This breadth ensures models generalize to undocumented legacy systems and data-lake imports without compliance concerns, since inference touches only metadata. The complete MLOps stack includes a FastAPI service with six typed prediction endpoints, an MLflow registry for model versioning and promotion, Prometheus and Grafana for golden-signal monitoring with 10 alert rules, Evidently for input-drift detection, and GitHub Actions CI running lint, format, and test suites. Models use multiple decision-tree classifiers, trained with grouped cross-validation (by database for keys, by table for normal forms) to prevent memorization. The service caches models by name, and the entire stack runs from a single Docker Compose configuration. This supports the primary use case: giving data engineers ranked, probability-scored candidates to confirm when recovering keys for Data Vault modeling.
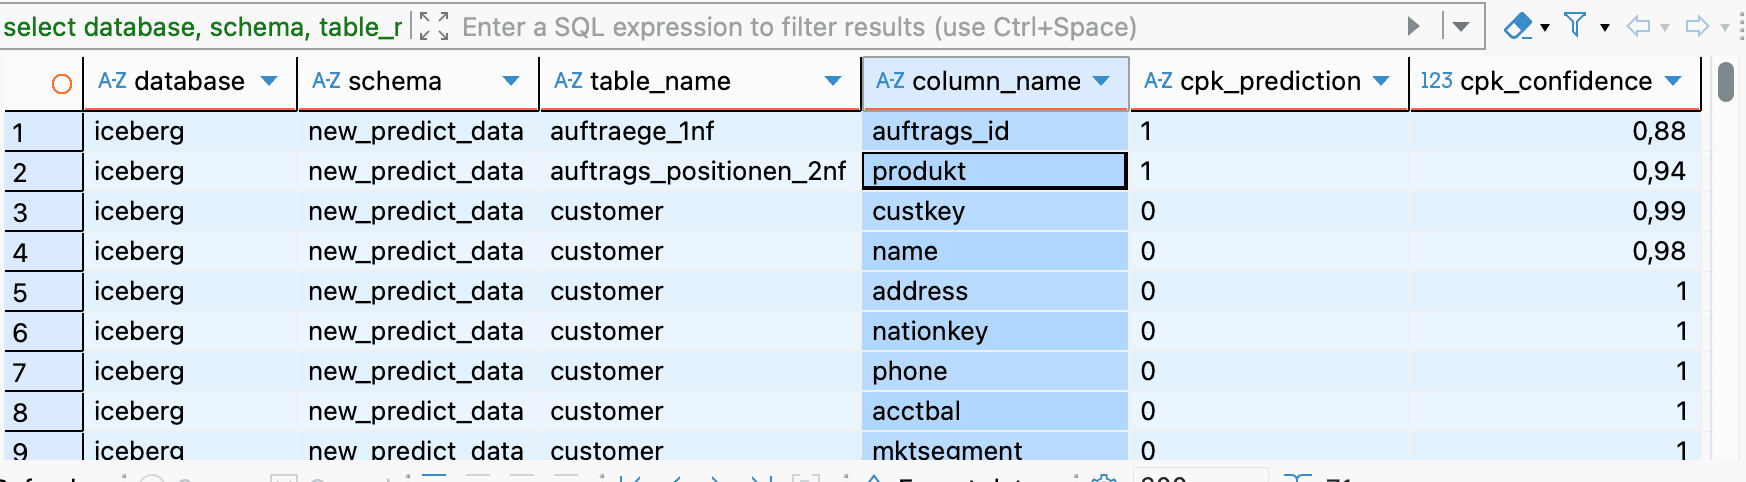
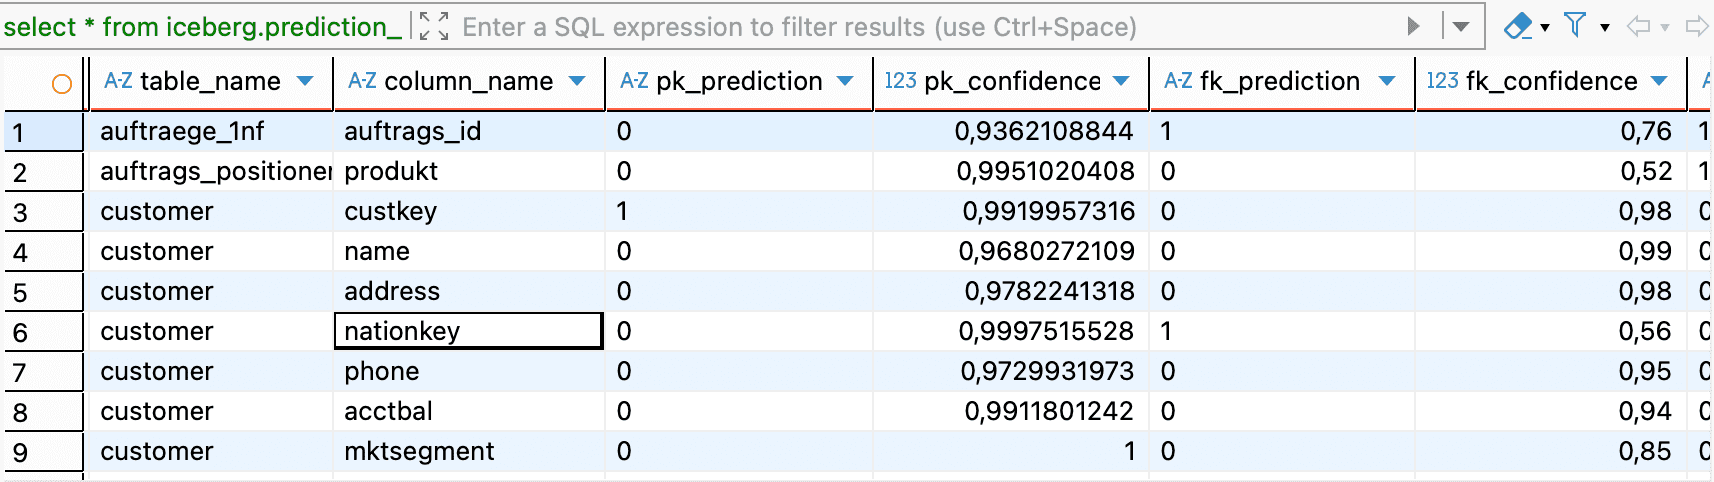
Provide semi-automated identification of Primary Keys, Foreign Keys, Normalization Forms, and Subject Areas by analyzing only database metadata and delivering probability-scored candidates to domain experts for schema properties. Accelerate data-modeling workflows—especially Data Vault implementations—where experts confirm and refine predictions rather than starting from scratch. Enable fast, compliant inference on regulated data (medical, financial). Build a production-grade MLOps system with experiment tracking, model versioning, comprehensive monitoring, and CI/CD to ensure model quality and operational reliability. Transform undocumented legacy systems and data-lake dumps into well-understood, modeled data assets.
The Team
- Christian Müller
Christian Müller: BI Consultant, Data Engineer, Data Vault and Data Warehouse specialist
- Nijiati
Nijiati: Programmer and Web Developer, specialized in Java and Automation
- Niklas Lorenz
Niklas Lorenz: BI Consultant, Data Engineer, Data Vault and Data Warehouse specialist
We AI-proof
your career


